×
[노타 x 래블업] AI PC에서 로컬 LLM을 어떻게 효율적으로 사용할까? |
10월 14일 오후 8시
Blog
Insights
ALL
Tech
Product
Events
Newsletter
Newsroom
ALL
Press Release
Media
Teamblog
ALL
Team Nota AI
Inside Nota AI
Nota AI Opinion
Developers
NetsPresso® ↗
Hugging Face ↗
Teamblog
en
ko
Jaehoon Lee
Technical Content Manager
Insight
Tech
September 18, 2026
|
15
min read
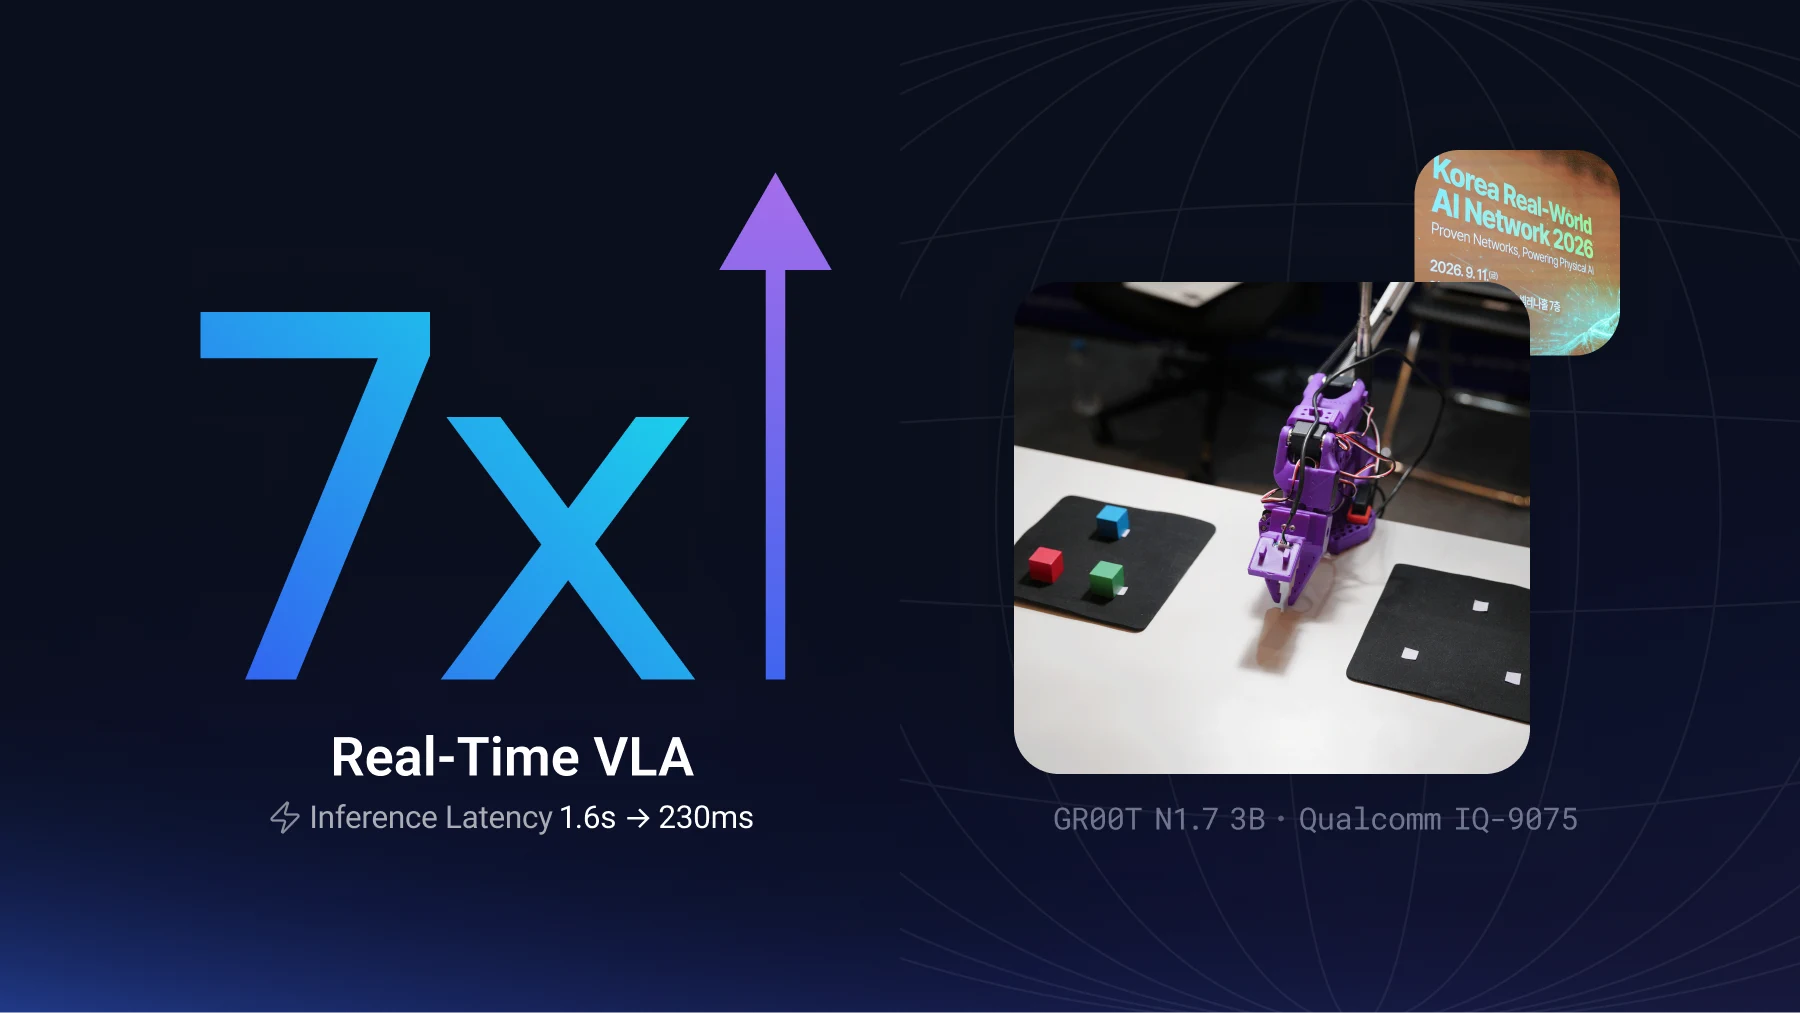
Running VLA Without a GPU: 1.6s to 230ms on a Qualcomm NPU
Tech
August 26, 2026
|
5
min read
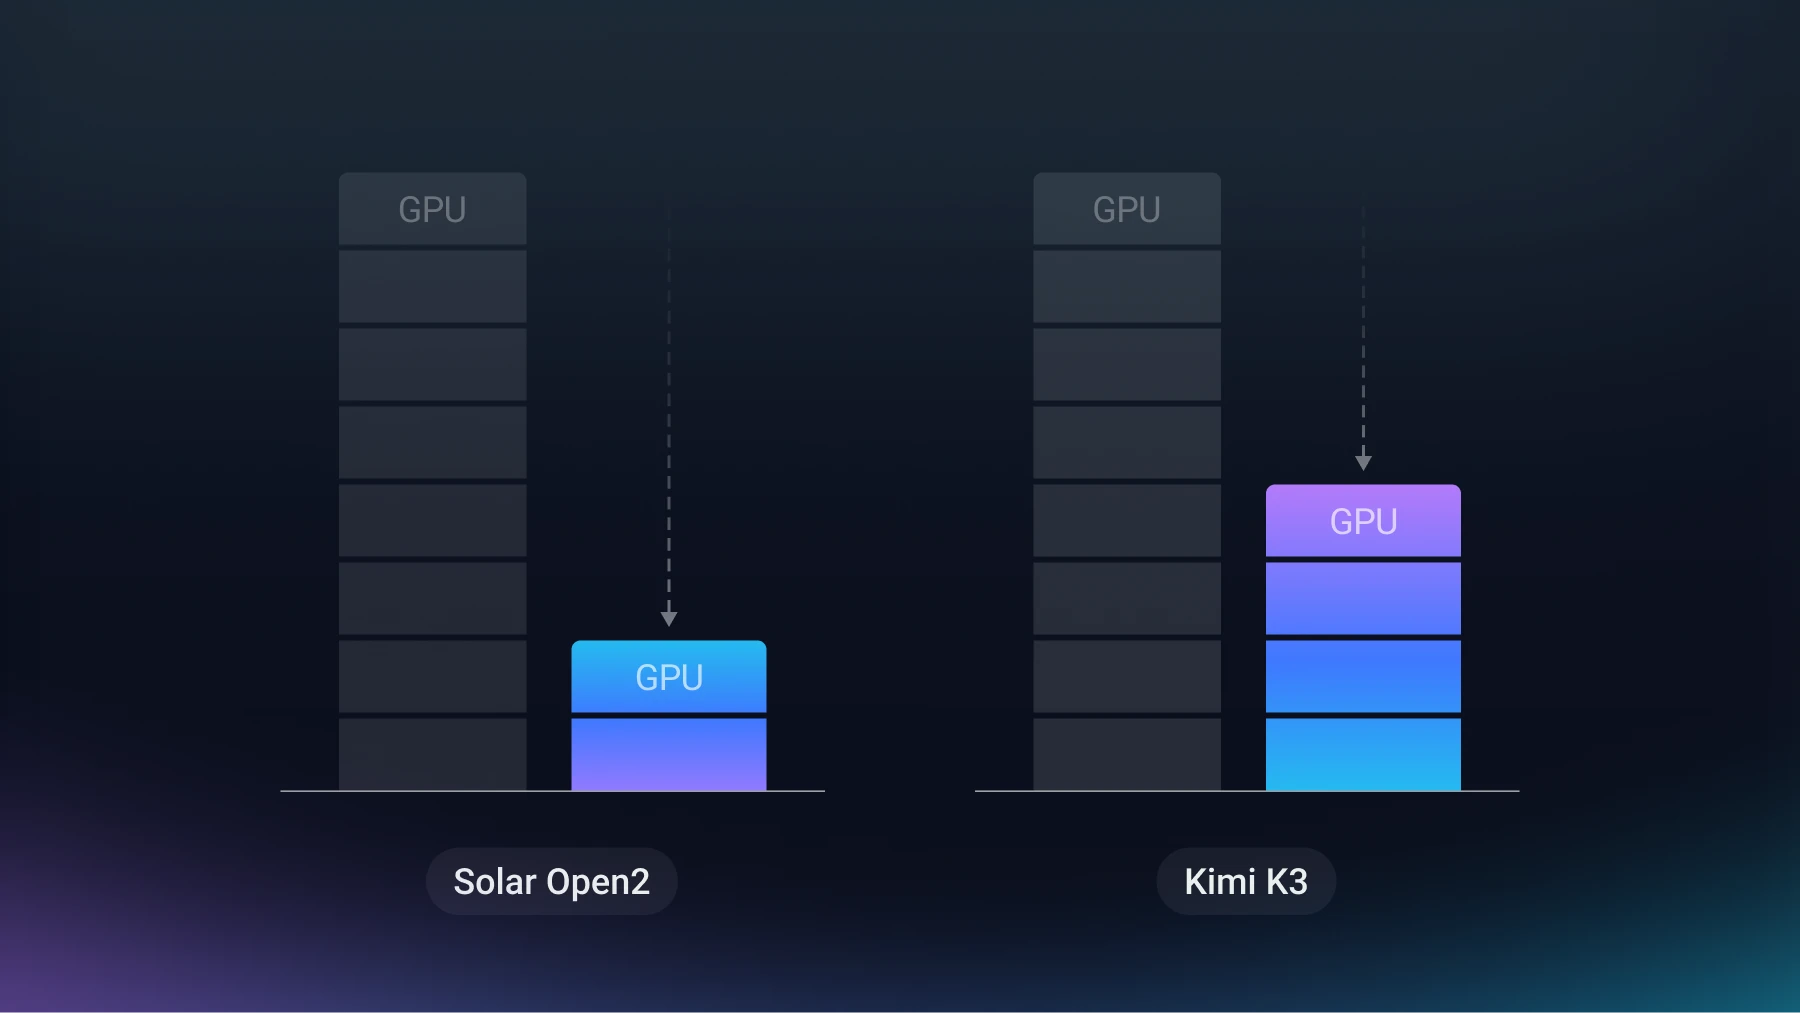
From Eight H100s to Two: The GPU Cost Savings of LLM Compression
Product
August 5, 2026
|
3
min read
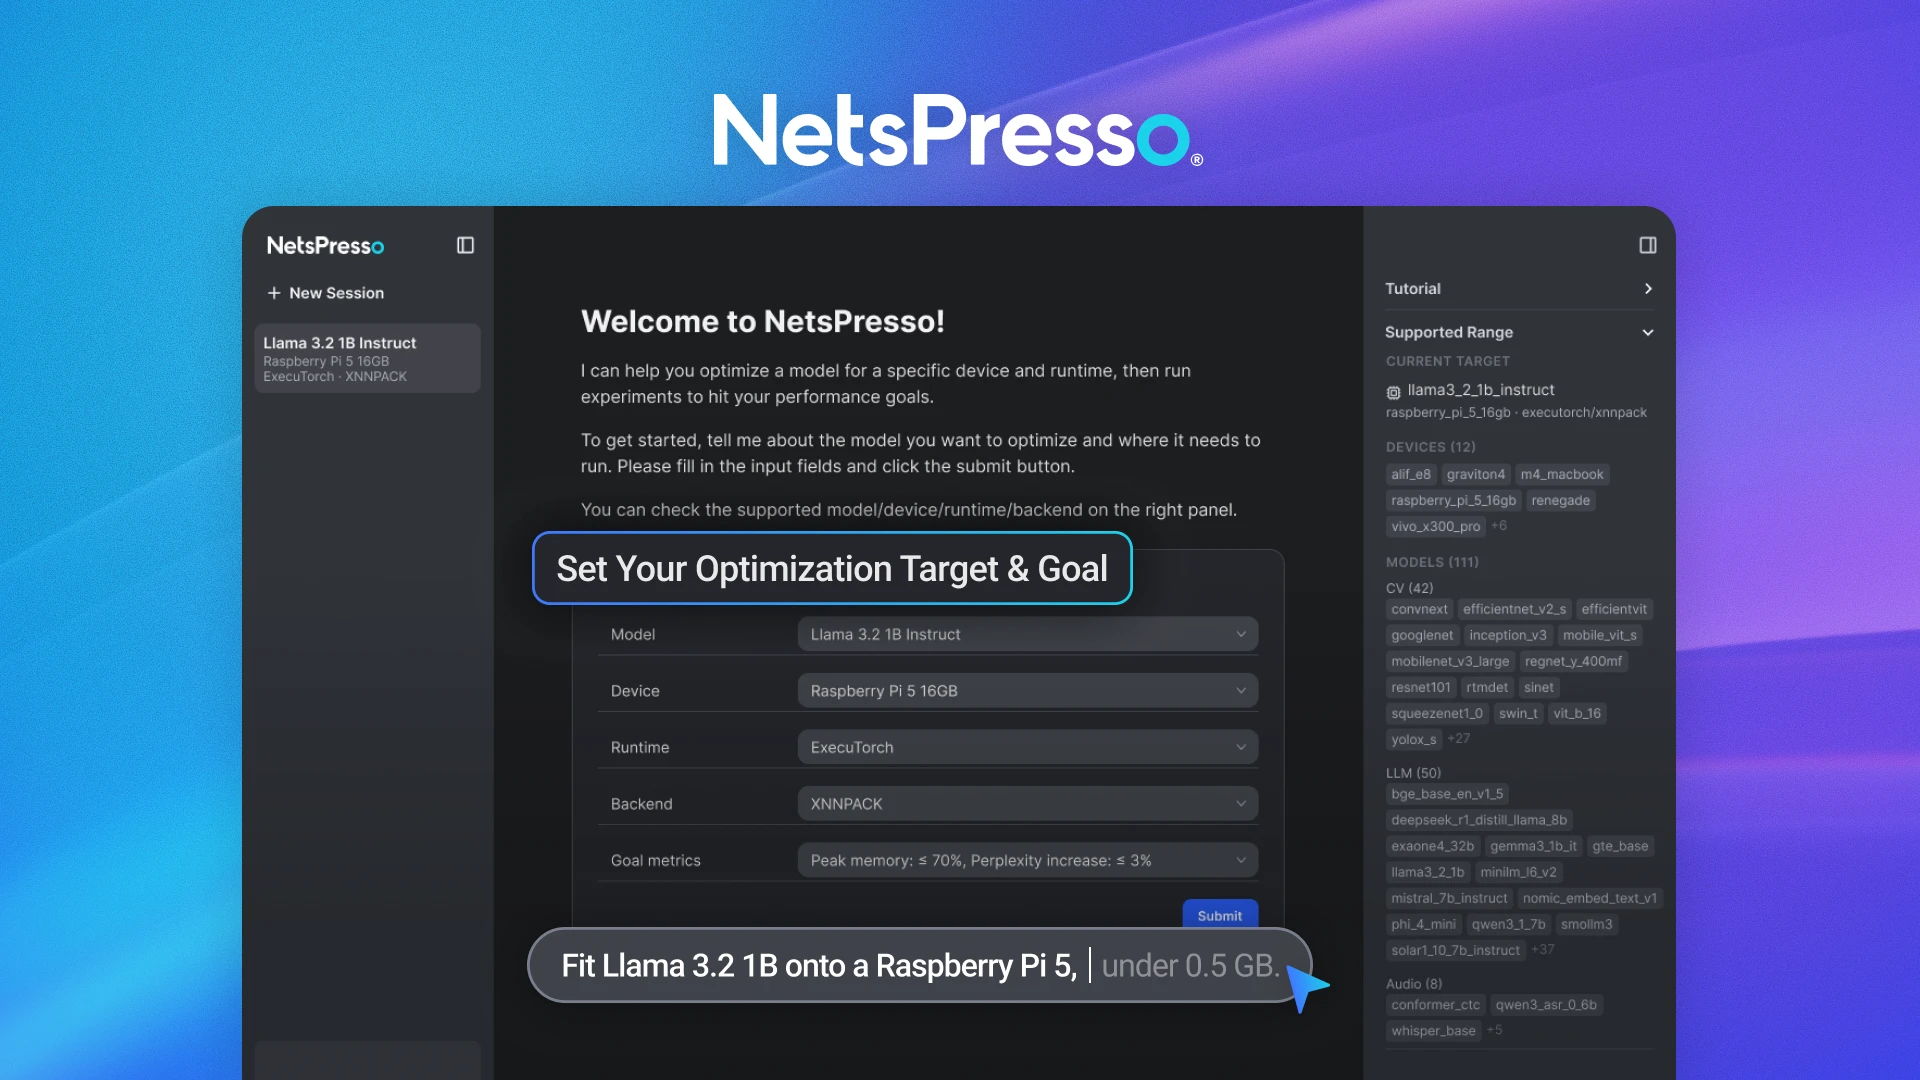
From Semi-Automatic to Fully Automatic: How NetsPresso Optimizes Models with an Agent
Events
July 30, 2026
|
4
min read
Nota AI Joins AMD's Robotics Partner Network as the Only Korean Company
Tech
July 15, 2026
|
5
min read
Running Llama 8× Faster on a Raspberry Pi: The KCC 2026 On-Device AI Optimization Challenge
Tech
July 3, 2026
|
4
min read
[NetsPresso® AQ Deep Dive] How to Quantize the K-EXAONE-236B Model to 4-Bit (NVFP4)
1
…
1 / 3
Culture
Team Nota AI
September 1, 2026
|
8
min read
What Six Months at Nota AI Looks Like
1
…
Stay Ahead with Expert Insights on Edge AI
Subscribe Now
Thank you! Your submission has been received!
Oops! Something went wrong while submitting the form.