The biggest concern when you plan to run an in-house AI agent on an on-premises LLM is GPU cost. A single card can cost tens of thousands of dollars, and once a server is in place, its configuration is hard to change. If you come up short on GPUs, you have to buy more; if you have too many, budget is tied up in equipment no one uses. Waiting for prices to drop is not a safe bet either. According to Bloomberg, NVIDIA plans to raise the price of servers shipping in early 2027 by more than 15%, citing rising memory costs. That is why the number of GPUs to buy should be worked out precisely before purchase.
Organizations that cannot use cloud APIs because of security or regulation, such as those in finance and the public sector, have to build their own Private AI. In a survey that asked companies why they moved AI workloads on-premises, security and governance (42%) was cited more often than cost savings (25%). If your organization is one of these, there is something to check before you buy GPUs.
You have to decide the GPU configuration yourself, and that is not easy. Some teams review the configuration together with a GPU server vendor, but a hardware consultation alone rarely produces the answer. The number of GPUs you need depends on how far the model can be optimized. The GPU count is set by the total memory the model and its conversation context (KV cache) take up, and that total varies widely depending on how far the model can be reduced while keeping its accuracy. If you set the GPU count from the original model size alone, you leave out the share that quantization and pruning could cut, and even after the server arrives you still need people to handle model optimization and serving configuration.
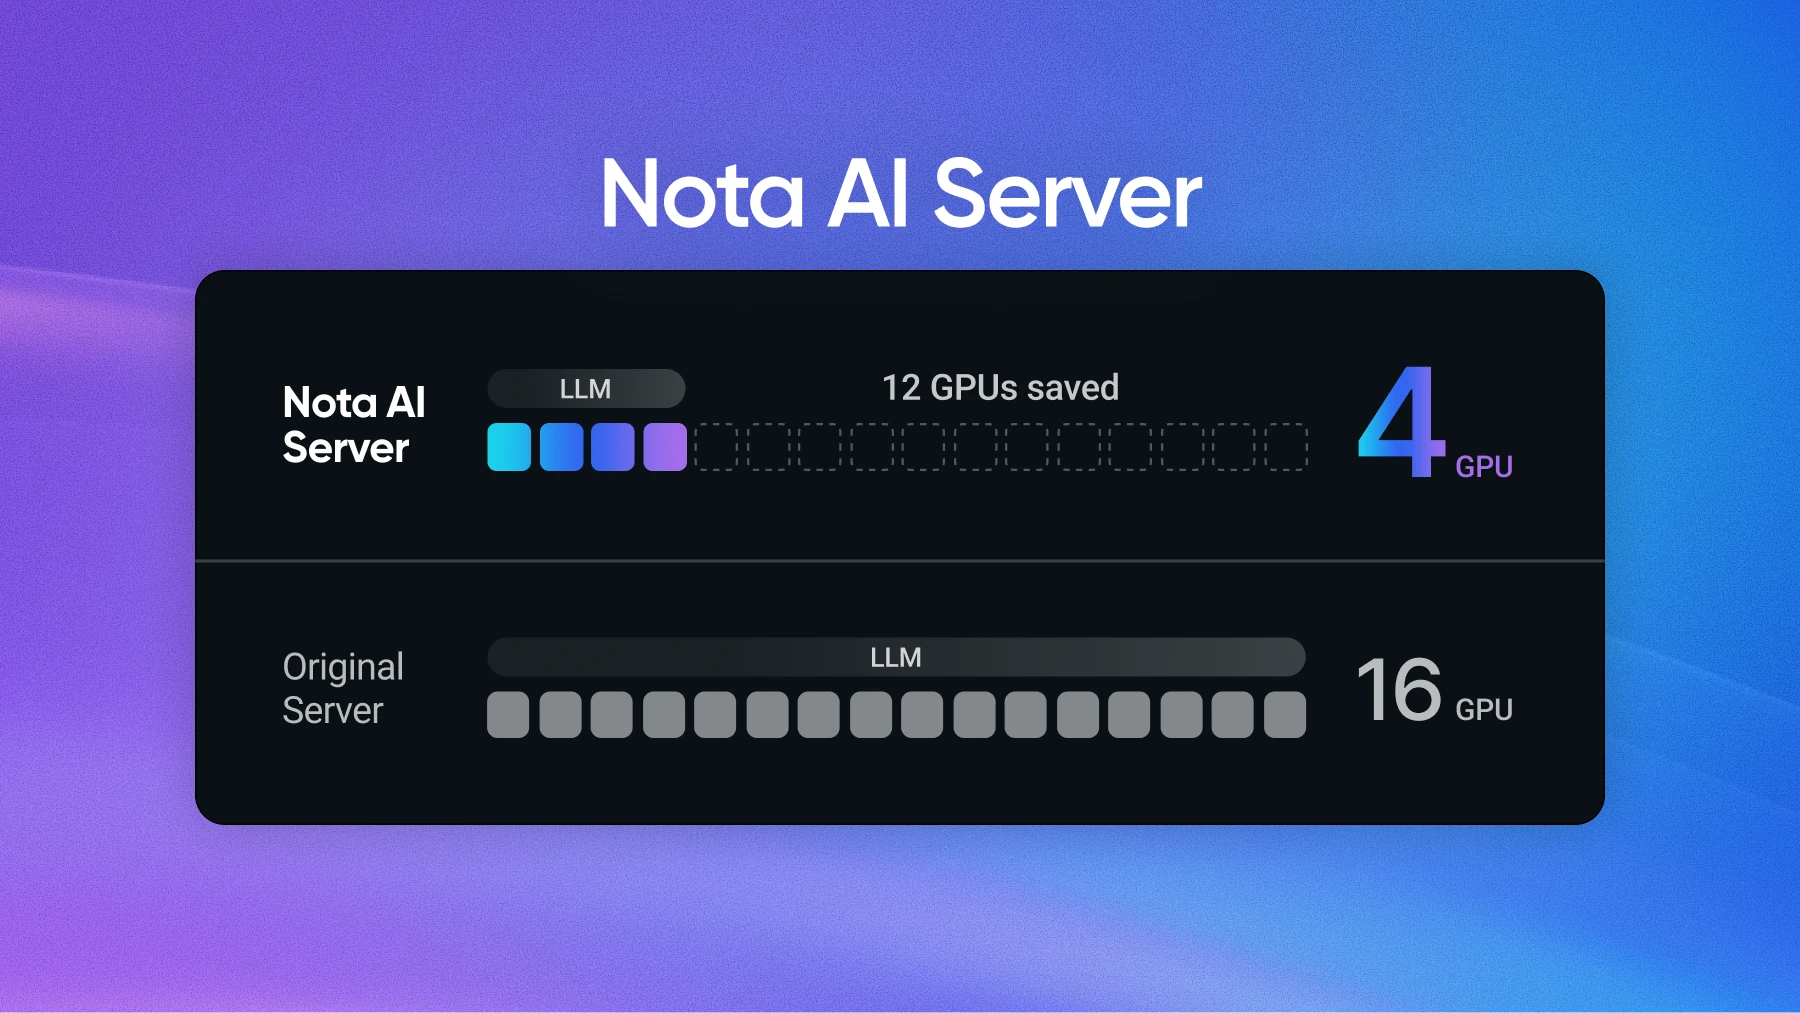
Nota AI Server is an on-premises LLM server that optimizes the model your organization wants to run for your GPU setup and delivers it with serving already configured. Under a workload of 20 users each using 128K context at the same time, it runs a 250B-class model, which needs 16 GPUs at original precision, on just 4 GPUs. You run the same service on a quarter of the GPUs, and cutting 12 GPUs also cuts equipment cost, power, and rack space along with them. This article looks at how to decide the GPU configuration when you build an on-premises LLM, and what changes when you use Nota AI Server.
An on-premises LLM is not finished once you buy a server and load a model onto it. You first have to decide how many GPUs to buy, and two things are hard to pin down at that point: the memory that optimization can cut, and the memory that grows with real usage conditions.
The common way to size it is to multiply the parameter count by the bytes per value for a given precision, then add the KV cache that stores the conversation context plus a margin. How far you can lower the precision changes the GPU count a lot. Taking the same model from BF16 down to 4-bit cuts the weight memory to a quarter. But whether accuracy holds up after quantization or pruning can only be known by testing it on that specific model, and testing needs GPUs and evaluation work first. So at the purchase stage, many teams size for original precision (BF16) or FP8, where accuracy is less of a worry, and the memory that optimization could cut is left out of the estimate.
The memory that grows with usage conditions has to be calculated separately for each model architecture. As concurrent users increase and the context handled at once gets longer, the KV cache grows, and its size differs widely from model to model. Under a workload of 20 concurrent users each using 128K tokens of context, Qwen3.6-27B quantized to 4-bit is 16 to 19GB, but its KV cache needs about 80GB. Because the KV cache is set by the structure of the attention layers rather than the total model size, it ranges from 13.5GB (Gemma 4 26B-A4B) to 240GB (Solar Open 100B) under the same conditions. Solar Open 100B fits on a single GPU when quantized to 4-bit, but because of this KV cache it is configured with 4 GPUs. This is a case where the GPU count is set by usage conditions rather than model size.
While optimization reduces required memory, higher concurrency and longer context windows increase it. So the GPU count is only settled by calculating how far optimization can be applied together with the real usage conditions. Nota AI Server finishes the optimization and accuracy validation of the target model before the GPUs are purchased, and sets the GPU count based on that result. So how many GPUs can you actually save by optimizing first?
Nota AI Server keeps accuracy loss under 1% in most cases while cutting VRAM by up to 73.5% (Solar Open 2, including the KV cache). The techniques applied are 4-bit quantization (INT4 and NVFP4), and some models also apply Global Pruning. These techniques are based on Nota's research on Mixture-of-Experts (MoE) quantization (DREAM-MoE, SRA-MoE) presented at an ICML 2026 workshop. In an MoE model, the router selects a subset of experts to compute for each input, so if quantization error changes the router's choice, accuracy drops. Nota calibrates the quantization parameters and the router together so that the expert ranking the original model produced is preserved, and builds the calibration data so that even rarely used experts are calibrated evenly.
A representative case is the 250B-class Solar Open 2 (15B active, MoE). This model applies Global Pruning and 4-bit quantization together, cutting a configuration that needed 16 RTX PRO 6000 cards down to 4. Looking at the model weights alone, that is a drop from 500.6GB to 117.8GB (INT4), the kind of size that lets you put a model that needed 8 H100s onto 2.
The accuracy difference is small. With 4-bit quantization alone, the average over 15 benchmarks dropped from 81.57 (original, BF16) to 81.17, a decrease of 0.40 points. For pruning, which experts you keep is what drives accuracy. Because MoE models have different proportions of redundant experts in each layer, removing the same proportion in every layer also damages the sensitive ones. Global Pruning compares the importance of experts across the whole network and sets a different number of experts to keep in each layer. As a result, the model with Global Pruning applied still averaged 83.39 across three high-difficulty reasoning benchmarks, close to the quantization-only model (83.99) and higher than the REAP method (78.79), which removes experts uniformly at the same proportion. Even with pruning added, accuracy does not change much. Both the quantized model and the Global Pruning model are published on Hugging Face.
Processing speed also went up. In measurements published on Hugging Face, Solar Open 2 with Global Pruning (NVFP4) reached a token throughput of 1.23x the original with a single concurrent user and 1.49x with 32 users, measured on 4 B300 cards. This is thanks to the time to generate one token dropping from 28.4ms to 17.8ms. Time to first token (TTFT) dropped from 0.98s to 0.74s with a single user, and remained comparable at 32 users (4.9s vs. 5.3s). In short, shrinking the model does not lower processing speed, and the throughput gain grows as concurrent users increase.
The GPUs you save can cut the upfront investment, or you can take on more users with the same GPUs or serve other models alongside.
Cutting the GPU count does not end with making the model smaller. You also have to decide which GPUs the smaller model runs on and how it is split across them before you have a real configuration.
The goal of optimization is not to trim memory bit by bit but to bring it down to the size where the required GPU count drops by one step. Tensor parallelism, which spreads a model across several GPUs, can only increase the GPU count in fixed steps set by the model structure, such as 2, 4, or 8. Solar Open 2 quantized to INT4 is 162.9GB including the KV cache, which is 2.9GB over the capacity of two H100s (160GB). It cannot be split across three, so it needs four. Reducing it to 137.8GB with Global Pruning lets it fit on two. A 25GB difference in memory is what separates two H100s from four.
Even at the same 4-bit precision, the format determines which GPUs can run it. INT4 (W4A16) cuts only the weights to 4-bit and computes in 16-bit, so it runs on an H100 or an L40S. NVFP4 (W4A4) computes activations in 4-bit floating point as well, which can raise processing speed further, but it requires the FP4 compute units of Blackwell-generation GPUs (RTX PRO 6000, B300). That is why in Table 2 the L40S configurations use INT4, while the Blackwell configurations choose between INT4 and NVFP4 depending on the model.
The same goes for pruning. Applying Global Pruning leaves a different number of experts in each layer, as shown in Figure 4. For Kimi K3, a trillion-scale model, the version with 50% of experts removed keeps anywhere from 350 to 717 experts across its 92 MoE layers. Standard vLLM assumes every layer has the same number of experts, so it cannot serve this model as is. Nota provides a modified vLLM model definition that reads the per-layer expert count. When the expert count differs by layer, expert parallelism (EP), which assigns experts to separate GPUs, cannot be used either, so the configuration is reworked with tensor parallelism. The optimized model files alone cannot be served directly on standard vLLM, which is why the serving environment must be tailored alongside them.
Nota AI Server is installed with the optimization and serving configuration above already done. If you build it yourself, you have to bring in the GPU server, then quantize the model, validate accuracy, pick a serving engine that fits the model, set up parallelism across several GPUs, and test the concurrent-user load, one step after another. The fewer people an organization has dedicated to serving, the bigger this difference is. The standard configuration is as follows.
Models are pre-configured with 4-bit quantization and verified compatibility, and the serving engine is set to vLLM or SGLang, whichever fits the model. When an optimized model loads onto a single GPU, two independent instances are run per GPU to secure throughput and fault isolation, and tensor parallelism (TP) is applied only to large models that do not fit on one card. Operational features that multiple departments need to share, such as authentication, usage limits, request queues, and monitoring and logging, are also included by default.
Once installation is done, the system goes through an acceptance test that includes a load check with 20 users sending requests at the same time at 128K context. In-house systems only need to call a single OpenAI-compatible API endpoint from day one of deployment, and in-house tools built to the OpenAI API format can connect by changing the call address. That means there is almost no separate development to do on the in-house side. For closed networks, Air-gap packaging is provided, so you can install without an external internet connection and keep models and data running only inside your own servers.
The lineup has three options by model scale: Standard, Advanced, and Premium. The reason one lineup can span models and GPUs as different as tens of billions of parameters up to trillion-scale, and L40S up to B300, is that Nota has experience optimizing many chips and models from edge devices to servers. Every configuration is designed around 20 concurrent users and 128K per session.
Even within the same tier, the right model differs by task. In Standard, for example, Qwen3.6-35B-A3B configured on L40S fits when there are many users and budget is the priority, while Gemma 4 31B fits when document understanding matters, as with contracts and scanned documents. The Solar Open series is a set of models Nota officially optimized for the government's Sovereign AI program.
Premium is the Kimi K3 we looked at earlier, reduced with Global Pruning. Removing 50% of the MoE experts brought an 8-card B300 configuration down to 4, and on the same 50% setting it scored higher on 3 of 4 public benchmarks compared with REAP, Cerebras's MoE expert pruning method. For organizations that put quality first, there is also an option that removes only 25% of the experts and runs on 6 B300 cards. Both models are published on Hugging Face.
Models or hardware not in the lineup can also be assessed for optimization potential and expected results through a PoC. The scope can extend to open-source or in-house LLMs and VLMs of your choosing, NVIDIA GPUs outside the standard list, AI accelerators such as NPUs, edge hardware, and integration with existing private-cloud or hybrid environments. Nota works alongside you from optimization through PoC to deployment.
For organizations that cannot use cloud APIs because of security or regulation, the GPU configuration is a decision that is hard to reverse once made. If you set the GPU count from model size alone, you leave out the share that optimization could cut, and even after purchase, model optimization and serving configuration remain on your plate. Nota AI Server optimizes the model your organization wants to run for your GPU setup and delivers it with serving already done, so you can run Private AI on fewer GPUs from day one.
Check the configuration you need before you buy GPUs. Tell us the model you want to run, the number of concurrent users, and the length of the documents you handle, and we will review the GPU configuration and expected savings for those conditions, and support you in confirming them directly through a PoC if needed.