×
[노타 x 래블업] AI PC에서 로컬 LLM을 어떻게 효율적으로 사용할까? |
10월 14일 오후 8시
Blog
Insights
ALL
Tech
Product
Events
Newsletter
Newsroom
ALL
Press Release
Media
Teamblog
ALL
Team Nota AI
Inside Nota AI
Nota AI Opinion
Developers
NetsPresso® ↗
Hugging Face ↗
Teamblog
en
ko
Hancheol Park
AI Research Engineer
Insight
Tech
August 26, 2026
|
5
min read
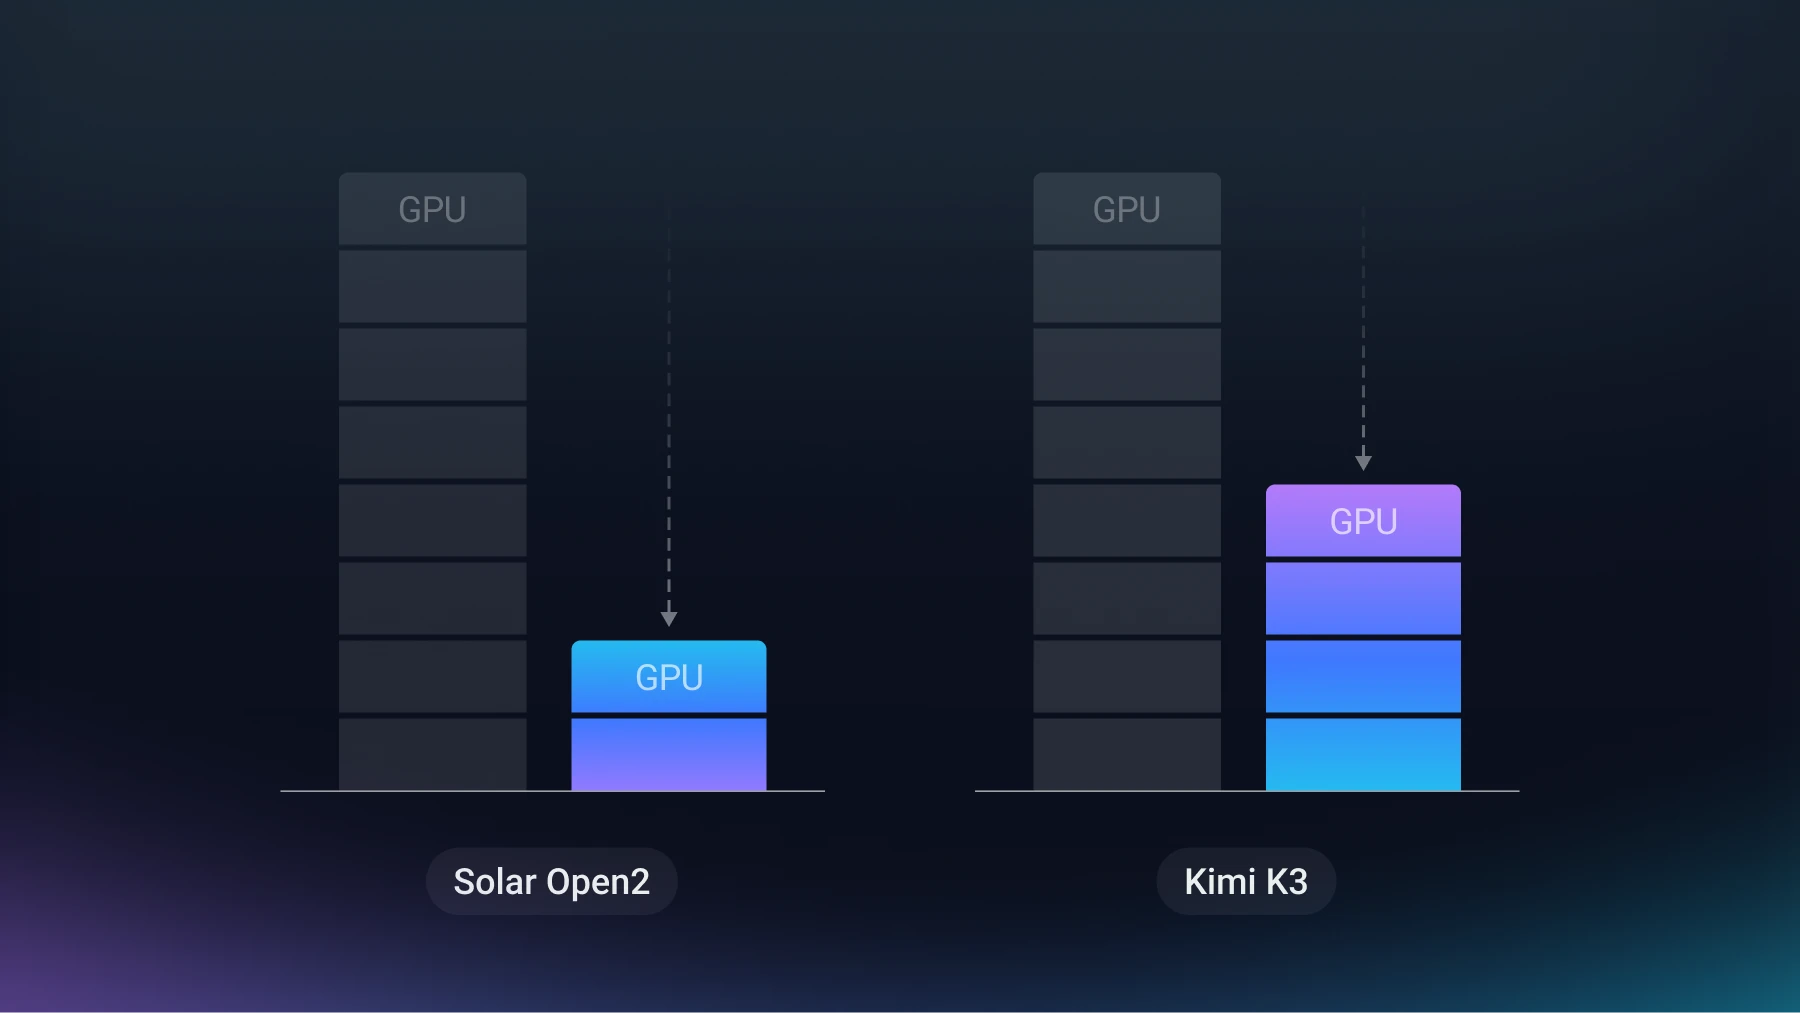
From Eight H100s to Two: The GPU Cost Savings of LLM Compression
Tech
June 12, 2026
|
3
min read
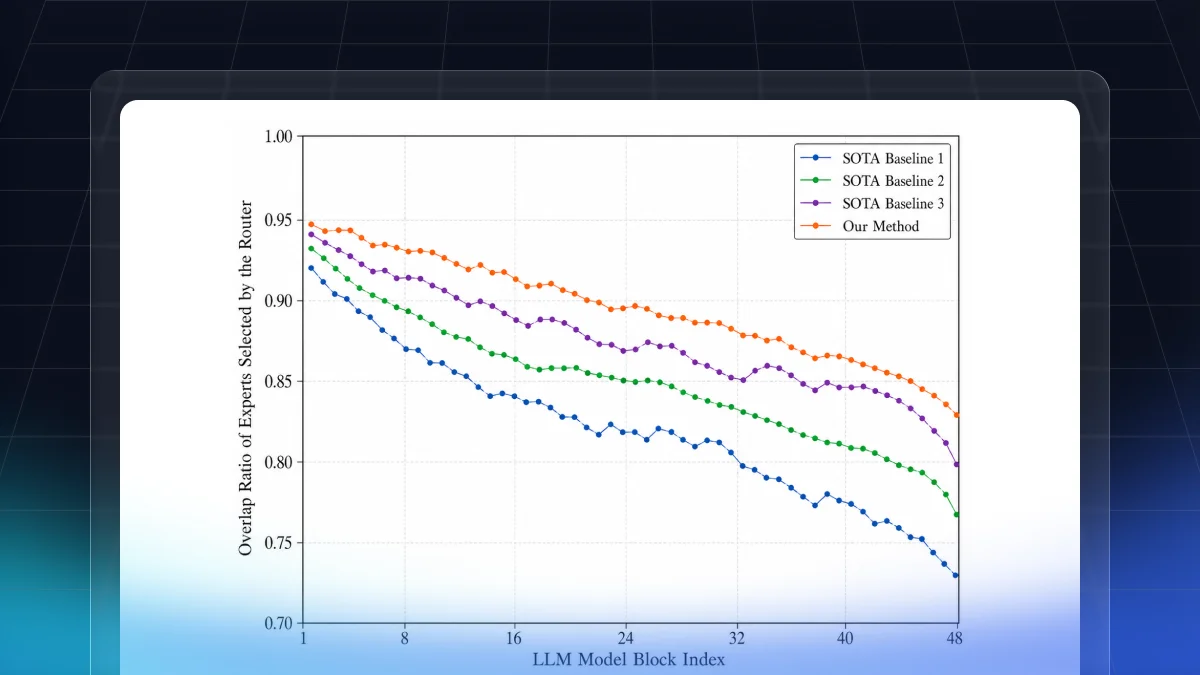
Two papers discussing quantization methods specialized for MoE LLMs, accepted to an ICML 2026 workshop
Tech
August 2, 2024
|
5
min read
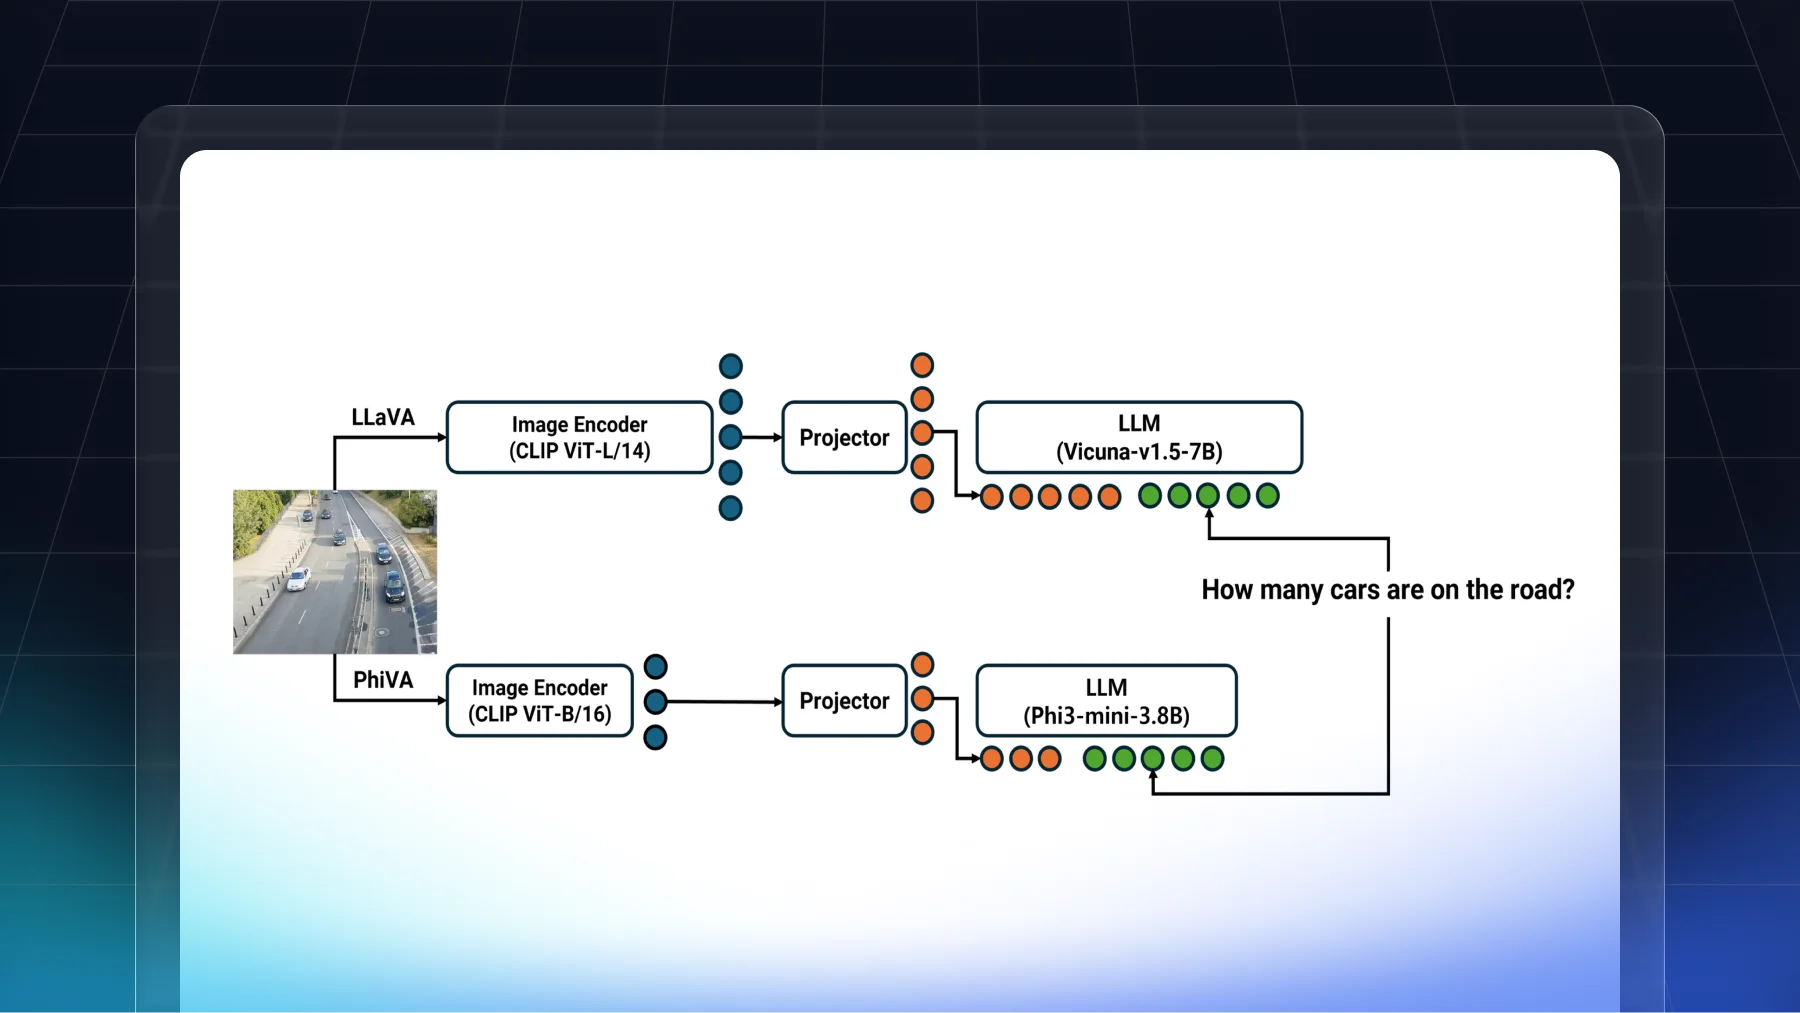
Deploying an Efficient Vision-Language Model on Mobile Devices
Tech
March 13, 2026
|
6
min read
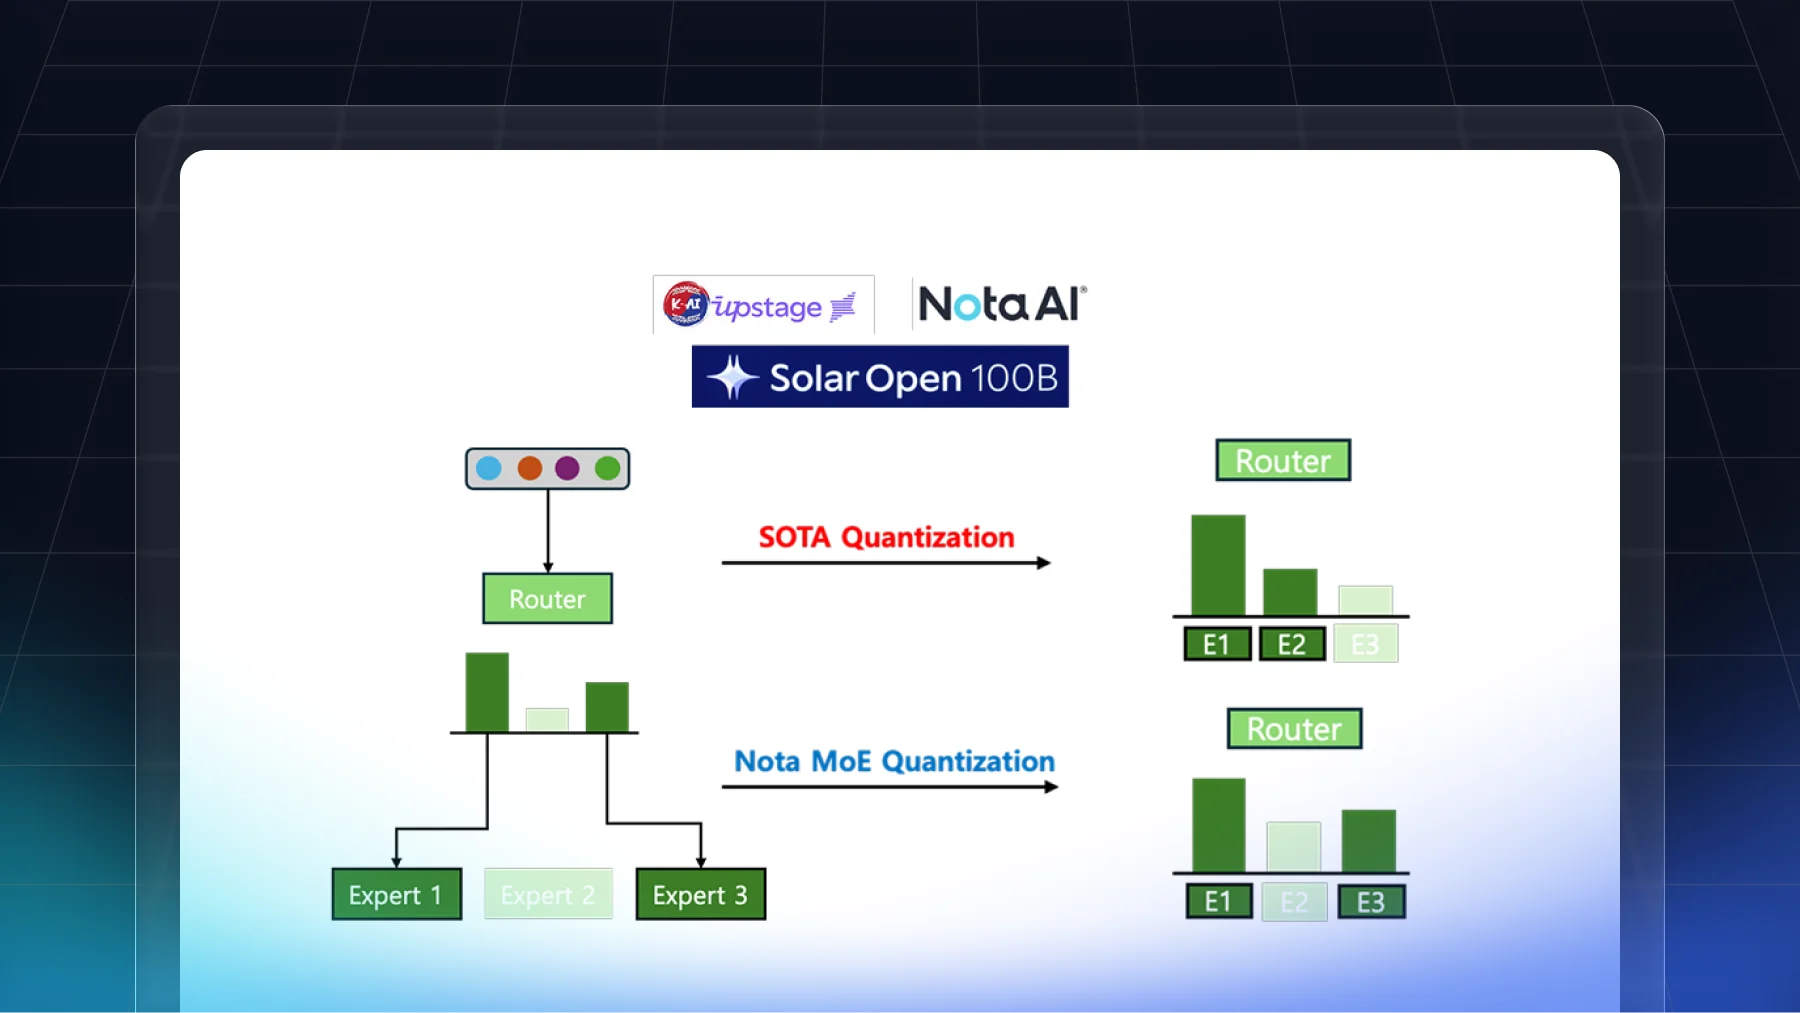
NotaMoEQuantization: An MoE-Specific Quantization Method for Solar-Open-100B
Tech
February 10, 2025
|
6
min read
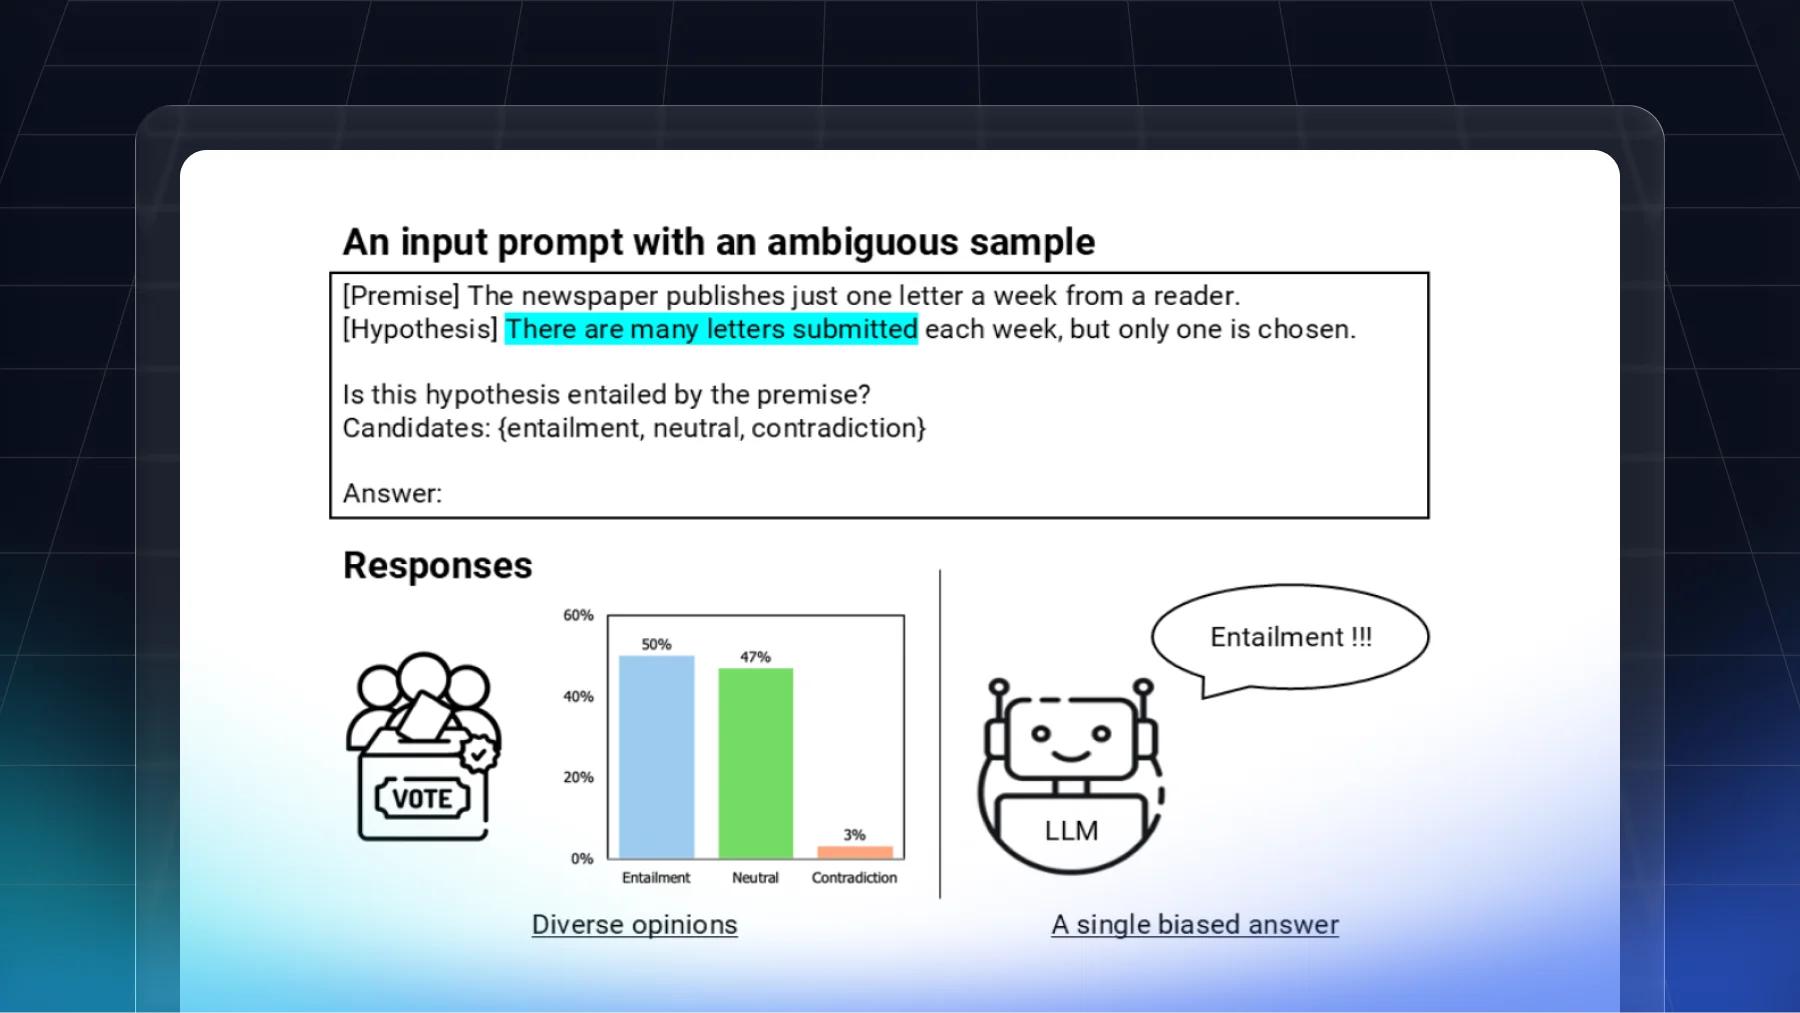
Where do LLMs Encode the Knowledge to Assess the Ambiguity?
Tech
February 25, 2025
|
5
min read
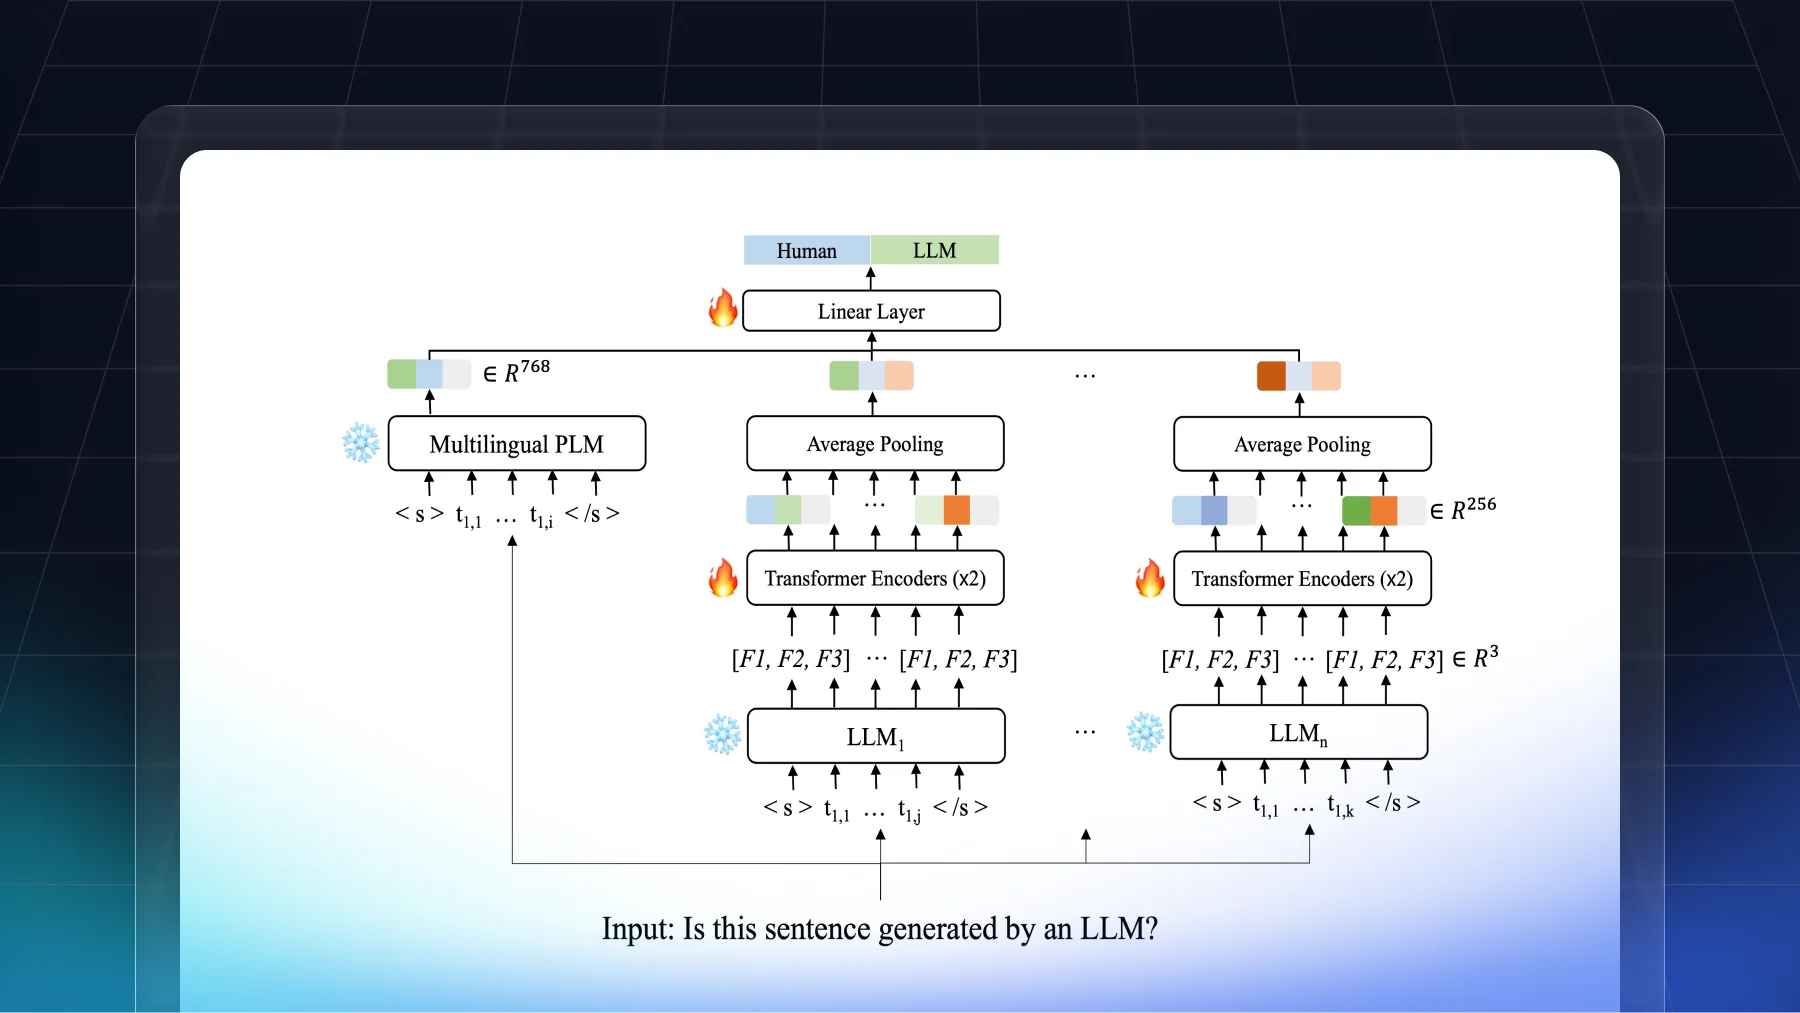
A Study on Detecting LLM-Generated Multilingual Content
1
…
Culture
1
…
Stay Ahead with Expert Insights on Edge AI
Subscribe Now
Thank you! Your submission has been received!
Oops! Something went wrong while submitting the form.